Elementary Math in Elementary School: The Efect Of Interference On Learning The Multiplication Table Part 2
Nov 01, 2023
These exclusions left 17 participants who completed the study and whose results are reported below (age range 6;1–7;11, mean=7;0, SD=0;5): two in second grade, 14 in first grade, and one in kindergarten senior year. None of them knew any of the 16 multiplication facts taught in the study (Additional file 1: Table S7a).
Over time, our memory is inevitably affected. However, age is not the only determining factor. Research shows that with proper exercise and maintaining a positive attitude, we can maintain good memory and cognitive function, even at older ages.
When we are young, our brains are more active and responsive. This is mainly because when children learn and experience new things, their brain neurons are fully stimulated. This stimulation promotes connections and signal transmission between neurons, thereby improving our learning and memory abilities.
However, as we age, our brains gradually lose certain neurons and connections, which can lead to a decline in memory and cognitive function. However, we can activate brain neurons and promote connections between neurons through appropriate exercise, thereby improving our memory and cognitive abilities. For example, doing some memory training, such as puzzles, Sudoku, etc., can improve our memory and concentration.
Also, it’s important to keep a positive attitude. Research shows that happiness and positive emotions can promote connections between neurons in the brain, thereby improving our cognitive function and memory. Therefore, we should maintain positive emotions as much as possible, interact more with family and friends, and participate in some interesting activities to make ourselves feel happy and satisfied.
In conclusion, age is not the only determinant of our memory and cognitive function. With proper exercise and maintaining a positive attitude, we can maintain good memory and cognitive function even at older ages. Let us face life positively, stay optimistic and healthy, and let our brains be fully stimulated and exercised. It can be seen that we need to improve our memory. Cistanche deserticola can significantly improve memory, because Cistanche deserticola can also regulate the balance of neurotransmitters, such as increasing the levels of acetylcholine and growth factors. These substances are very important for memory and learning. In addition, meat can also improve blood flow and promote oxygen delivery, which can ensure that the brain receives sufficient nutrients and energy, thus improving brain vitality and endurance.

Click know ways to improve brain function
Stimuli
Each child learned the same 16 multiplication facts, in which both operands were between 3 and 9. There were no ties (N×N). The smaller operand appeared first. The 16 facts were grouped into 4 sets with 4 facts in each: two sets with low similarity among the facts, and two sets with high similarity (i.e., the level of similarity was manipulated within participant).
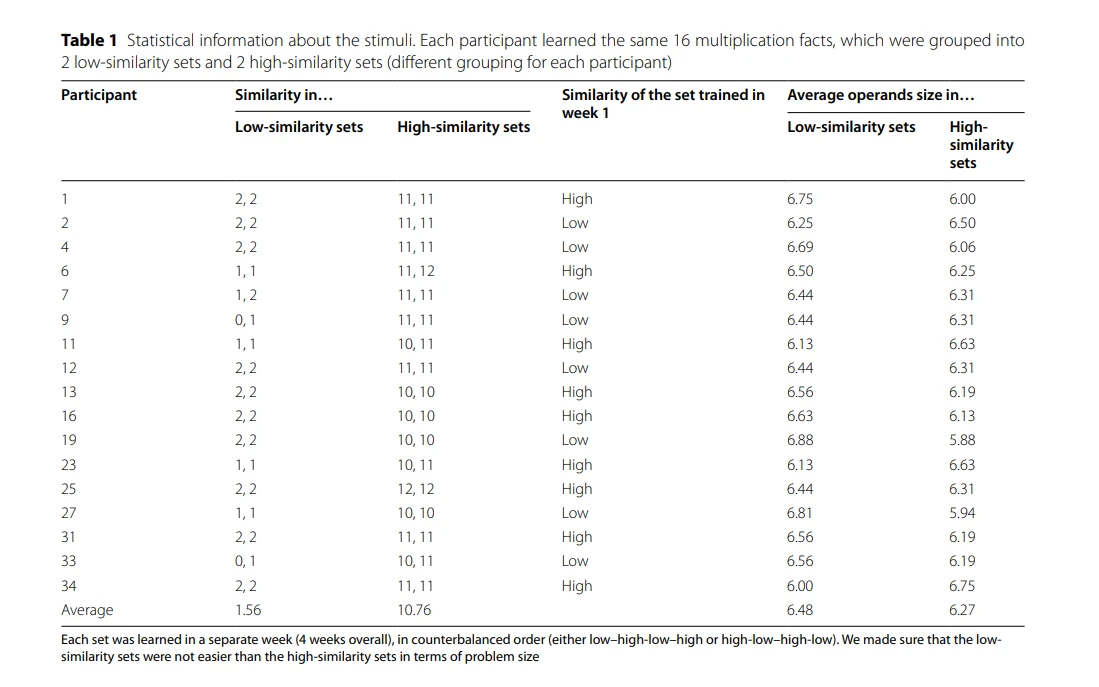
All children learned the same 16 facts, but the grouping of the facts into 4 sets was different for each child (Additional file 1: Table S4). The per-child grouping was random and was designed to maximize the difference between the low-similarity and the high-similarity sets. We also ensured that similarity was not confounded by problem size—i.e., that the low-similarity sets were not consistently easier due to smaller operands.
The average operand size in the low-similarity sets was slightly higher than in the high-similarity sets (Table 1. For the excluded participants, there was a very small difference in problem size, Additional file 1: Table S5). The participants were not told about the similarity manipulation. The experimenters knew about the manipulation but they were not told, for each specific week, whether it was high-similarity or low-similarity.
Computing similarity
There are many possible methods to compute the similarity among facts in a given set. Different methods rely on different theoretical assumptions about several issues, e.g., whether the similarity index should reflect the similarity between digits or between words, whether it should be sensitive to the role of a particular digit/word as an operand or a result, etc. (cf. Appendix of Dotan & Friedmann, 2019).
In the absence of a systematic comparison between the different similarity computation methods, we used a simple method that previous studies have shown to be effective (De Visscher & Noël, 2013, 2014a, 2014b; Dotan & Friedmann, 2019). First, the similarity between two facts was defined as the number of digit pairs that appeared in both facts, irrespective of the digits’ position in the fact and their role as operand or result. For example, the facts 8×7=56 and 8×3=24 have no common digit pair (only the digit 8 appears in both) so their similarity is 0. The facts 3×4=12 and 3×7=21 have 3 common digit pairs (1–2, 2–3, and 1–3) so their similarity is 3.
Then, the similarity index for a set of 4 facts was computed by summing the pairwise similarities of all 6 fact pairs in the set. For the multiplication table up to 9×9, this similarity index essentially reflects the overlap between the digits of the two facts (operands and response), with no penalty for a single overlapping digit and a nonlinear penalty for additional overlapping digits.
Procedure
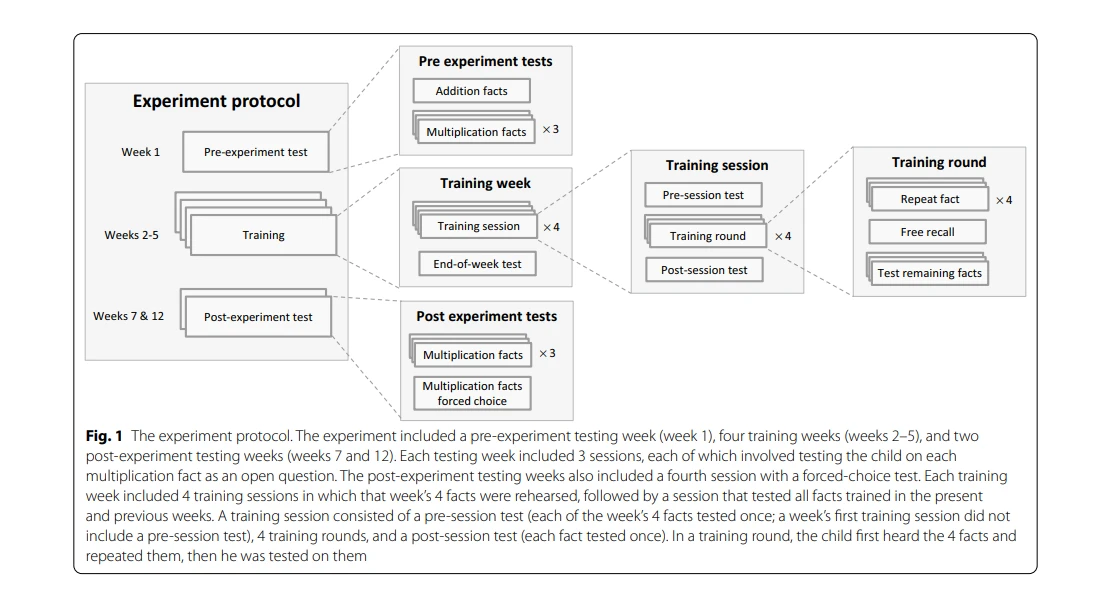
The experiment sessions were held during the COVID-19 pandemic period, which prevented face-to-face meetings, so they were done in one-on-one online video meetings with voice over a phone call. To reduce the effects of inter-individual differences, the design was fully within-participant, i.e. all children underwent the same procedure. The experiment started with one week of pre-experiment tests (week 1; Fig. 1).
At this time the children had not yet started learning, so obviously, they almost invariably answered “I don’t know”. The pre-experiment test was aimed primarily to verify that the participants had no prior knowledge of multiplication. Four training weeks followed immediately (weeks 2–5). After a delay of one week, there was a post-experiment test (week 7), and another post-experiment test after an additional delay of 4 weeks (week 12). The experiment weeks were not aligned with calendar weekdays.
To increase the relevance to school-learning situations, we aimed to examine the specific effect of similarity on learning (as opposed to its effect on testing/retrieval, as in Campbell, 1987), so we applied similarity manipulation during the learning sessions but not during the test sessions. In the test sessions, similar and dissimilar facts were mixed.
Training period (weeks 2–5)
Each training week included 5 sessions, held on 5 different days: 4 training sessions (approximately 20 minutes each) in which that week’s 4 facts were rehearsed, followed— with a gap of at least one day—by a weekly test session. Each training session consisted of a pre-session test, 4 training rounds, and a post-session test.
Training rounds
Each training session included 4 training rounds, which were the core of learning. Each round started with the experimenter saying each fact and the participant repeating it. Errors were corrected immediately. The participants then retrieved all facts they remembered (exercise and result), and the experimenter corrected any errors. Finally, the experimenter asked about any fact that the child did not retrieve, with immediate error correction. Whenever an error was corrected, the participant repeated the correct fact (exercise and result) until saying it correctly. The order of presenting the facts was random and was different for each presentation of the 4 facts (counterbalanced within participants).
Pre‑ and post‑session tests in the training sessions
These tests were held at the beginning and end of each training session. A week’s first training session did not include a pre-session test, as the child had not yet started learning that week’s facts. Both tests had the same structure: the child was tested once on each of the week’s 4 facts by asking “How much is X times Y?” After the child responded to all 4 facts, errors were corrected: for each fact in which the child erred or did not know the answer, the experimenter said the exercise and the solution, and the child repeated it. If the child repeated incorrectly, the experimenter asked to repeat the fact over and over again, until it was repeated correctly.
Weekly test sessions during the training period
In the last session of each week, the child was tested on each of the facts learned so far in the current and previous weeks—i.e., on 4 facts at the end of the first training week, and all 16 facts at the end of the 4th training week. This weekly test included 2 rounds, each presenting all tested facts in random order (different order in each round), with the limitation that the 4 facts of the current week were the first in each round. No feedback was given except general encouragement. In these weekly tests and the pre-experiment and post-experiment tests (described below), low-similarity and high-similarity exercises were mixed in the same session.
From these weekly tests, we analyzed only the most reliable responses. To determine how reliable each particular response is in terms of informing about the effect of similarity, two main factors need to be considered. First, in each week the participants were tested on the facts learned in the current week and the preceding weeks, but we analyzed only the responses to the current week’s facts, to avoid confounding with the time elapsed since learning. Second, in each weekly test session, the participants were tested on each fact twice, in two rounds.
From these two rounds, we deemed the first round as more reliable, because presumably, this round reflects the participant’s long-term knowledge better than the second round (below, we shall see results indicating that this was indeed the case). The responses in the second round may be confounded by local effects— e.g., the participants may simply repeat their responses from the first round. Thus, throughout the results section, the weekly test analyses refer only to the first-round responses, unless explicitly said otherwise.
Pre‑experiment testing (week 1)
Week 1 included 4 testing sessions, held on 4 separate days. In the first session, the child was tested on 10 single-digit additions and 7 subtractions with a single-digit subtrahend and result. The results of these addition/subtraction tests are reported in Additional file 1: Tables S5 and S6. In each of the next 3 sessions, the child was tested on 43 multiplication facts (each fact once per session, i.e. 3 times during the week): all operand pairs between 2×2 and 9×9 (36 facts, the larger operand appeared second), and 7 facts with 0 or 1 as operands. The question was “How much is X times Y?” No feedback was given except general encouragement.

Post‑experiment testing (weeks 7 and 12)
Each of these two weeks included 4 testing sessions, held on 4 different days. The first 3 sessions tested the multiplication facts knowledge like in the pre-experiment tests. The 4th session was a two-alternative forced-choice test. The distracter for a fact was the result of another fact from the same 4-fact set. In week 7, the forced-choice test included a single round with 16 questions—each trained fact appeared once.
In week 12, the test included two rounds, each round asking once about each of the 16 trained facts. Untrained facts were not presented in the forced-choice tests. No feedback was given except general encouragement.
Statistical analyses
For each fact, we defined two measures reflecting its similarity to the 3 other facts in the same set. Numeric Similarity is the specific fact’s average similarity to the 3 other facts in the set, and Similarity Level is the set’s classification as low-similarity or high-similarity. The grouping of facts into sets was different for each child, so these parameters were computed for each child.
To examine the effect of similarity on the participants’ accuracy, we submitted the per-fact accuracy (correct/ incorrect) to a logistic linear mixed model (LLMM) with the Participant and Fact as random factors. The critical within-participant factor was Similarity, the specific similarity predictor being either Numeric Similarity (numeric factor) or Similarity Level. These LLMMs also included two within-participant covariates accounting for the problem size: the average and product of the operands (but in all the critical analyses, the results were essentially the same when removing the two problem-size factors, and also when additionally removing the Fact random factor). Other LLMM configurations are detailed below.
In the few cases wherein an LLMM reached a singular ft, which may result from over-fitting or did not converge, we first tried z-scoring each predictor. If that did not help, we removed the Fact random factor (similar results were obtained when keeping this factor). To examine the significance of a particular factor or interaction, we used a log-likelihood ratio test and compared the full LLMM to a model in which that factor/interaction was removed. For these comparisons, we report the test statistic 2(LL1− LL0), which follows a χ2 distribution (LL0 and LL1 denote the log-likelihoods of the reduced model and the full model), and the corresponding p-value.
Results
Learning dissimilar facts is easier
In the end-of-week tests, as predicted, accuracy in the low-similarity weeks was higher than in the weeks with similar facts by 13.7% (Fig. 2a), i.e., by a factor of 1.25. To examine the similarity effect statistically, we used the logistic linear mixed model described in Methods. The dependent variable was the per-fact accuracy, the participant and fact were random factors, and there were 3 within-subject factors: similarity (either Numeric Similarity or Similarity Level, in two separate analyses), and the two problem-size factors as covariates (sum and product of the operands).
The effect of similarity was significant (with Similarity Level factor: χ2 (1)=7.34, p=0.007, odds ratio=0.41, Fig. 2a; with Numeric Similarity factor: χ2 (1)=10.47, p=0.001, odds ratio=0.43, Fig. 2b; detailed LLMM results in Additional file 1: Table S10a, b). Because the number of participants was not large, we verified that the effect of similarity was significant also when comparing the high- and low-similarity sets using statistical tools simpler than a linear mixed model—paired t-test (t(16)=1.90, one-tailed p=0.04, Cohen’s d=0.48) and Wilcoxon Signed Rank test (W=91, one-tailed p=0.04).
An effect of similarity was found also among the excluded participants (specifically, for the 6 participants whose amount of data sufficed to test a similarity effect; Additional file 1: Figure S2). Thus, as predicted, it was harder for the children to learn facts that were similar to each other, and it was easier for them to learn dissimilar facts.
The results above refer to the participants’ first round of responses in each weekly test session, as we considered the responses in this round to reflect the participants’ long-term knowledge more reliably than the responses in the second testing round. Still, the similarity effect was observed also in the second round (same LLMM, Numeric Similarity effect: χ2 (1)=6.72, p=0.01, odds ratio=0.49; but the effect was not significant when using the Similarity Level factor, χ2 (1)=2.48, p=0.12; Additional file 1: Figure S3, Table S11). The similarity effect in the second-round responses was smaller than in the first-round responses, in line with our assumption that the first round is a better reflection of the learning and the similarity effect.
Critically, the similarity effect originated in the learning that occurred during the experiment and cannot be attributed to pre-existing knowledge. In the pre-experiment tests on multiplication facts (in week 1), the average accuracy on the to-be-trained facts was virtually zero, leaving no room for a similarity effect: 2.7% in the low-similarity sets and 2.5% in the high-similarity sets. The 0.2% difference between the low- and high-similarity sets was not significant (a logistic linear mixed model did not converge, so we used a paired t-test: t(16)=0.32, one-tailed p=0.37).
Contrary to findings with older children (De Visscher & Noël, 2014a), the participant’s sensitivity to similarity (hereby StS, Fig. 2a) did not predict their overall accuracy. To examine this, we entered the per-participant overall accuracy as the dependent variable in multiple linear regression. The critical predictor was the participant’s StS, defined as Δaccuracy between low- and high-similarity sets (Δaccuracy>0 denotes higher sensitivity).
A second predictor controlled for the fact that each child learned the multiplication facts in a different grouping, with different specific levels of similarity. This predictor was defined as similarity = SimH − SimL, with SimH and SimL denoting the participant’s average within-set numeric similarity of the two high-similarity sets and the two low-similarity sets, correspondingly.
If the participant’s StS affects the overall accuracy, the St's predictor should have a significant negative effect. This was not the case: neither predictor had a significant effect (StS: b=−0.55, one-tailed p=0.21; Δsimilarity: b=−0.12, one-tailed p=0.30). Still, crucially, high sensitivity to similarity predicted low performance in the high-similarity sets: in a similar regression, in which the dependent variable was accuracy in the high-similarity sets, the St's predictor had a significant negative effect (b=−0.61,one-tailed p=0.006), with no effect of Δsimilarity (b=−0.57, one-tailed p=0.20).
Such an effect of StS was not found when the dependent variable was accurate in the low-similarity sets (StS: b=0.39, i.e., opposite to the predicted direction; Δsimilarity: b=−0.57, one-tailed p=0.20). In sum, sensitivity to similarity disrupted learning specifically in high-similarity conditions.
The findings above clearly show that it is easier to learn dissimilar facts than similar ones. In the subsequent sections, we examine why this is so.
The similarity effect arises specifically from the grouping of facts in the training sessions
What is the origin of the similarity effect? Our assumption, presented in the Introduction, was that the similarity effect originated in the specific grouping of facts into weekly sets during the learning time. In particular, we assumed that high similarity between the facts in a given week (hereby, “within-set similarity”) would disrupt learning. Correspondingly, the similarity index we defined captures the similarity between each fact and the 3 other facts in the same week.
An alternative view is that learning is disrupted by the similarity between the current week’s facts and the facts learned in previous weeks.

This resembles the idea proposed by de Visscher and Noël (2014b): they assumed that the multiplication facts are learned in a certain order and that learning is modulated by the similarity between each fact and all earlier facts in this “learning list”. A similarity index reflecting this alternative view should capture the similarity between each fact and all the facts in the previous weeks.
For more information:1950477648nn@gmail.com