Traffic Sign Recognition Based On The YOLOv3 Algorithm Part 3
Jan 19, 2024
3.3. Generating Priori Frames Based on K-Means Clustering Algorithm
The anchor mechanism was implemented in YOLOv2, and the number of anchors was increased to nine in YOLOv3 to make the generated candidate regions more similar to the genuine labeled frames and boost the detection network's recall.
There is a strong relationship between marked frames and memory. Marking frames can help us establish a fixed, regular, and orderly memory framework, making it easier to memorize large amounts of information. For example, when learning a language, we can use marked frames to memorize new words and grammar rules. When reviewing history, we can use marked frames to memorize historical events and timelines. In this way, we can make abstract knowledge more concrete and understandable.
At the same time, marking frames can also stimulate our brain's associative ability, thereby enhancing our memory. Because our memory is based on association and connection, by establishing marked frames, we can more naturally connect new knowledge with existing knowledge, deepening memory and understanding.
Human memory ability can be trained and improved. Through constant practice and the use of memory techniques such as marking frames, we can improve our memory and better cope with complex information and tasks in life and work.
In short, marking frames is a very effective memory technique. It can help us remember important information more quickly and accurately. It can also stimulate our associative ability and improve our memory. Let us actively use marked frames to continuously improve our memory skills! It can be seen that we need to improve memory, and Cistanche deserticola can significantly improve memory because Cistanche deserticola is a traditional Chinese medicinal material that has many unique effects, one of which is to improve memory. The efficacy of minced meat comes from the various active ingredients it contains, including acid, polysaccharides, flavonoids, etc. These ingredients can promote brain health in various ways.

Click Know to improve short-term memory
It was not appropriate to use the original anchor, since traffic signs are primarily small and medium targets, with fewer large targets in the TT100K dataset. For a specific dataset, choosing a suitable initial anchor can improve the detection effect, make the network easier to learn, and increase the detection rate of the bounding box.
The flow of the K-means clustering algorithm to obtain candidate boxes is shown in Figure 7.
In the TT100K dataset, the enhanced YOLOv3 network structure included a feature prediction scale, resulting in four scales and twelve anchors: (4, 5), (5, 6), (7, 7), (7, 13), (8, 8), (9, 10), (11, 12), (13, 14), (16, 17), (20, 22), (27, 29), and (41, 44).

4. Experiments and Analysis of Results
4.1. Dataset and Evaluation Indicators
There are a few big, publicly available traffic sign datasets, the majority of which use the GTSDB, but the GTSDB is not the same as Chinese traffic signs. CTSDB, CCTSDB, and TT100K, among others, are Chinese traffic sign datasets.
The CCTSDB was expanded based on CTSDB, and its categories were divided into warning signs, directional signs, and prohibition signs, without detailed classification of traffic signs.
The TT100K traffic sign collection was created in collaboration between Tencent and Tsinghua University. It offered thorough categorization and identification of traffic signs, covered various climatic and lighting circumstances, and was more accurate for actual driving situations.
Therefore, the TT100K traffic sign dataset was used in this paper, and some of the traffic signs and the category information are shown in Figure 8.

The TT100K dataset has 100,000 photos with a resolution of 2048 x 2048 pixels, although there are unlabeled traffic sign images, and some categories have only a few images or duplicate images, reducing the detection effect.
Therefore, this paper removed the unlabeled and duplicate traffic sign images from the dataset and selected 45 categories with a high number of traffic signs, where the 45 traffic sign categories were: pn, pne, i5, pll, pl40, po,pl50, pl80, io, pl60, p26, i4, pll00, pl30, il60, l5, i2, w57, p5, p10, ip, pl120, il80, p23, pr40.ph4. 5, w59, p12, p3, w55. pm20, pl20, pg, pl70, pm55, il100, p27, w13, p19, ph4, ph5, wo, p6.pm30, and w32, and the number of each traffic sign category is shown in Figure 9.

Figure 9 shows that even if 45 categories with a large number of traffic signs were chosen, there was still a significant imbalance in the amount of data between each category, resulting in poor model prediction accuracy. As a result, as illustrated in Figure 10, this work balanced and expanded the dataset by employing tactics such as color dithering, Gaussian noise, and image rotation to ensure that the amount of each category was as equal as feasible.

The Mosaic approach reads four images at a time, scales and alters the color gamut of each image, arranges them in four directions and then stitches the images together to create the target's true frame.
The enhancement method stitches four images, equivalent to calculating the parameters of four images with one input. This can reduce the number of images for batch input, reduce the training difficulty and training cost, improve the training speed, and largely enrich the number of samples in the dataset, which is conducive to learning.
in this paper, the evaluation metrics of the COCO dataset, including mAPou - 050APs, APM, AP, and several other metrics, were used to evaluate the performance of the model. In particular, most of the traffic signs in the TT100K traffic sign dataset belonged to small targets, so special attention needed to be paid to the detection accuracy of small targets. The specific meanings of the evaluation metrics are as follows:
AP: The area below the P-R curve, where P-R is precision and recall, respectively:
API = 0.50: When the IoU threshold is set to 0.50, it is the average of all categories of AP in the dataset, which is the evaluation index of the PASCAL VOC dataset and corresponds to APIoU = 0.50 in the COCO evaluation indexmAPloU= 0.50: When the loU threshold is set to 0.50, it is the average of all categories of AP in the dataset, which is the evaluation index of the PASCAL VOC dataset and corresponds to APloU = 0.5 in the COCO evaluation index.
APs: average value of mAP for small objects: area < 322, and loU = range (0.5, 1.00, 0.05)for a total of 10 oUs.
APm: medium objects: 322 < area < 962, and loU = range (0.5, 1.00, 0.05) mean value of mAP for a total of 10 IoUs.
AP: average value of mAP for large objects: area > 962, and loU = range (0.5, 1.00, 0.05for a total of 10 IoUs.
4.2. Experimental Results and Analysis
4.2.1. Improved YOLOv3 Comparison Experiment
Three YOLOv3 networks with enhanced methods were compared and tested in this study, utilizing the TT100K traffic sign dataset and input images that were 608 × 608 pixels in size. Figure 11 displays the map and AR of M-YOLOv3 trained on the TT100 dataset.
The detection results for various sizes of targets are shown in Figure 12 and Table 1. Among them, YOLOv3-DK adopted the strategy of improving the loss function DIoU loss and the re-clustering anchor; YOLOv3-SPP adopted the fusion space strategy of the pyramid pooling structure; YOLOv3-4l adopted the strategy of adding the fourth prediction feature layer with 152 × 152 scales; and M-YOLOv3 was the YOLOv3 network structure using all the improved strategies.

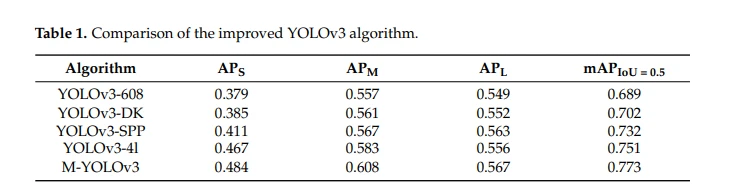
Table 1 and Figure 12 show that the average mean accuracy of the original YOLOv3 without employing any strategies was 68.9%. In contrast, the map of the upgraded YOLOv3 with all methods was 77.3%, an improvement of 8.4% in detection.
The DIoU loss function and re-clustering anchor technique enhanced detection accuracy by 1.3%; however, the improvement was due to faster loss function convergence during training, which made the target box regression more stable and improved the recall rate. More pronounced improvements in mAP were seen in YOLOv3, which included an SPP structure and achieved a 73.2%.
The SPP structure combined local and global characteristics, enhancing the feature map's ability to express itself and significantly increasing detection accuracy. Using the method of adding a fourth prediction feature layer with 152 × 152 scales, the mAP was also considerably improved.
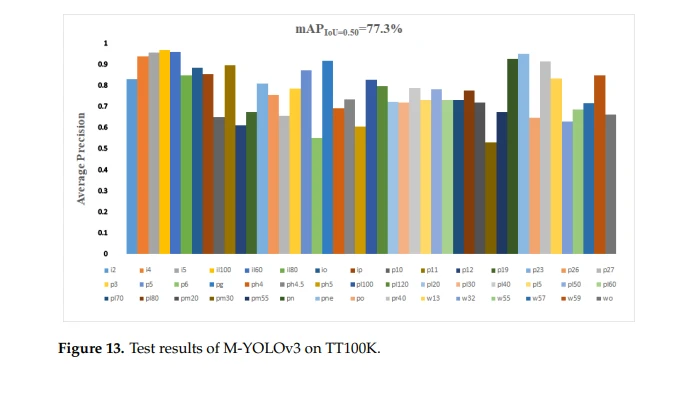
The accuracy of tiny-target detection was enhanced by 10.5% when compared to YOLOv3, which made full use of the shallow features in the network for small-target prediction, resulting in a considerably improved detection effect, but at the cost of increased network complexity and processing. The best improvement was M-YOLOv3, which combined the three improvement procedures and achieved an mAP of 77.3%, which is 8.4% higher than the original YOLOv30's average mean accuracy. Figure 13 depicts the test results of M-YOLOv3 on TT100K.
4.2.2. Comparison of the Improved YOLOv3 Algorithm with Other Algorithms
M-YOLOv3 was compared with several other classical target detection algorithms to further validate the detection recognition of the improved network, and the results are shown in Table 2.

Table 2 demonstrates that M-YOLOv3 had the highest mAP of 77.3%, and SSD had the best real-time performance, with an FPS of 42. Compared with the original YOLOv3 algorithm, the average precision mean was greatly improved, although the real-time performance was reduced. Compared with the one-stage algorithm SSD, mAP improved by 12%, but there was still a gap in real-time performance. Compared with the two-stage target detection algorithm Faster-RCNN, the FPS was improved to 22, and the mAP was also improved by 1.7%, which improved the detection speed, as well as the detection accuracy. The trials showed that M-YOLOv3 performed better in terms of detection accuracy and speed.
4.2.3. Improved Recognition Effect of YOLOv3 on Traffic Signs in a Special Environment
Due to various factors, such as strong light irradiation, nighttime, and special environments of traffic sign occlusion, that will affect traffic sign detection and recognition in real-world driving scenarios, it was also necessary to consider the model's recognition effect on traffic signs in special environments. In particular circumstances, the upgraded YOLOv3 model was employed to recognize traffic signs, as demonstrated in Figure 13.
In Figure 14, the detection effect of YOLOv3 is compared with that of M-YOLOv3 in a special environment. As shown in Figure 14(b1,c1), the YOLOv3 algorithm failed to detect the obscured traffic sign in the case of an obscured traffic sign, while the improved YOLOv3 algorithm accurately identified the obscured traffic sign; as shown in Figure 14(b2,c2), the YOLOv3 algorithm had problems of false detection and missed detection for traffic sign recognition under the environment of strong light irradiation, while the improved YOLOv3 algorithm recognized all the traffic signs accurately.

The improved YOLOv3 algorithm increased the fourth feature prediction scale for small targets, improving the detection effect of small targets, whereas the YOLOv3 algorithm had issues with missed detection and low confidence for small targets, as shown in Figure 14(b3,c3); in dimly illuminated environments, such as at night, the upgraded YOLOv3 algorithm recognized traffic signs, as illustrated in Figure 14(b4,c4); however the YOLOv3 method did not detect targets. As a result, under particular situations, the updated YOLOv3 algorithm still yielded better detection results.

5. Conclusions
A traffic sign detection and recognition network based on the modified YOLOv3 was suggested in this research, to address the difficulties of small targets being difficult to detect and low detection accuracy in traffic sign detection and identification tasks.
The new spatial pyramidal pooling structure enabled the fusion of local and global features in this study, as well as increased the fourth feature prediction scale for small targets to improve the detection effect of small targets. To make the target frame regression more stable, the DIoU loss was utilized, which had a faster convergence and was more consistent with target frame regression.
The detection network's accuracy was considerably improved by damaging the real-time network as little as possible. The mAP increased by 8.4 points. The upgraded YOLOv3 algorithm enhanced the network's complexity and lowered the detection speed. However, real-time detection is still a long way off; therefore, the next research area will be boosting detection speed to accomplish the effect of real-time detection.
Author Contributions: Methodology and writing-original draft preparation, A.L. and C.G.; formal analysis and investigation, Y.S.; data curation, N.X.; resources, A.L.; validation, W.H. All authors have read and agreed to the published version of the manuscript.
Funding: This project was supported by the Shandong Provincial Higher Educational Youth Innovation Science and Technology Program (Grant No.2019KJB019), the Shandong Provincial Natural Science Foundation of China (Grant No. ZR2021MF131, ZR2015EL019, and ZR2020ME126), and the National Natural Science Foundation of China (Grant No. 61601265 and 51505258). This project was funded by the China Postdoctoral Science Foundation (Grant No. 2021M701405), the Open Project of State Key Laboratory of Mechanical Behavior and System Safety of Traffic Engineering Structures, China (Grant No. 1903), the Open Project of Hebei Traffic Safety and Control Key Laboratory, China (Grant No. JTKY2019002), and the Major Science and Technology Innovation Project in the Shandong Province (Grant No. 2022CXGC020706).
Institutional Review Board Statement: Not applicable.
Informed Consent Statement: Not applicable.
Data Availability Statement: Not applicable.
Acknowledgments: We thank all the authors for their contributions to the writing of this article.
Conflicts of Interest: The authors declare no conflict of interest.

References
1. De la Escalera, A.; Armingol, J.M.; Mata, M. Traffic sign recognition and analysis for intelligent vehicles. Image Vis. Comput. 2003, 21, 247–258. [CrossRef]
2. Saadna, Y.; Behloul, A. An overview of traffic sign detection and classification methods. Int. J. Multimed. Information. Retr. 2017, 6, 193–210. [CrossRef]
3. Boumediene, M.; Cudel, C.; Basset, M.; Ouamri, A. Triangular traffic signs detection based on RSLD algorithm. Mach. Vis. Appl. 2013, 24, 1721–1732. [CrossRef]
4. Maldonado-Bascón, S.; Lafuente-Arroyo, S.; Gil-Jimenez, P.; Gomez-Moreno, H.; Lopez-Ferreras, F. Road-sign detection and recognition based on support vector machines. IEEE Trans. Intell. Transp. Syst. 2007, 8, 264–278. [CrossRef]
5. Bahlmann, C.; Zhu, Y.; Ramesh, V.; Pellkofer, M.; Koehler, T. A system for traffic sign detection, tracking, and recognition using color, shape, and motion information. In Proceedings of the IEEE Proceedings. Intelligent Vehicles Symposium, 2005, Las Vegas, NV, USA, 6–8 June 2005; pp. 255–260.
6. Ren, S.; He, K.; Girshick, R.; Sun, J. Faster R-CNN: Towards Real-Time Object Detection with Region Proposal Networks. Adv. Neural Information. Process. Syst. 2015, 28, 91–99. [CrossRef] [PubMed]
7. Liu, W.; Anguelov, D.; Erhan, D.; Szegedy, C.; Reed, S.; Fu, C.-Y.; Berg, A.C. SSD: Single Shot MultiBox Detector. In European Conference on Computer Vision; Springer: Cham, Switzerland, 2016; pp. 21–37.
8. Redmon, J.; Divvala, S.; Girshick, R.; Farhadi, A. You only look once: Unified, real-time object detection. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition, Las Vegas, NV, USA, 27–30 June 2016; IEEE: Piscataway, NJ, USA, 2016; pp. 779–788.
9. Wang, Z.; Guo, H. Research on traffic sign detection based on convolutional neural network. In Proceedings of the 12th International Symposium on Visual Information Communication and Interaction, Shanghai, China, 20–22 September 2019; pp. 1–5.
10. Han, C.; Gao, G.; Zhang, Y. Real-time small traffic sign detection with revised faster-RCNN. Multimedia. Tools Appl. 2019, 78, 13263–13278. [CrossRef]
11. Zhang, J.; Huang, M.; Jin, X.; Li, X. A real-time Chinese traffic sign detection algorithm based on modified YOLOv2. Algorithms 2017, 10, 127. [CrossRef]
12. Zhu, Z.; Liang, D.; Zhang, S.; Huang, X.; Li, B.; Hu, S. Traffic-sign detection and classification in the wild. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition 2016, Las Vegas, NV, USA, 27–30 June 2016; pp. 2110–2118.
For more information:1950477648nn@gmail.com